Verified October 8, 2026. Every price, limit, and benchmark below was checked against official docs and leaderboards on that date.
Originally published May 24, 2026.
People keep searching for this comparison, and most of what ranks is stale or vibes. The first version of this post was vibes too. This rewrite is numbers. One naming trap before we start: Codex here means OpenAI's current coding agent, not the retired 2021 model that once powered the original Copilot.
The 30-second version
| GitHub Copilot | OpenAI Codex | Claude Code | |
|---|---|---|---|
| What it is | Autocomplete, chat, and agents inside your editor and GitHub | OpenAI's coding agent inside ChatGPT, your terminal, and the cloud | Anthropic's agent-first coding tool, born in the terminal |
| Runs in | VS Code, Visual Studio, JetBrains, Xcode, Eclipse, github.com, CLI, mobile | ChatGPT desktop app, CLI, IDE extension, web, and via GitHub, Slack, Linear | Terminal, VS Code, JetBrains, desktop app, web, mobile |
| Models | 20+ model picker across OpenAI, Anthropic, Google, Microsoft, xAI, Moonshot | GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, and GPT-6 Luna; GPT-5.5 retires from Codex Oct 14, 2026 | Opus 5.5, Sonnet 5.5, Fable 5.1, Haiku 5.5 |
| Cheapest way in | Free tier, then Pro at $10 | ChatGPT Go at $8 | Pro at $20; no free tier |
| Persona | The neighbor next door | The road-trip uncle | The short-errand guy who became a general contractor |
Pricing
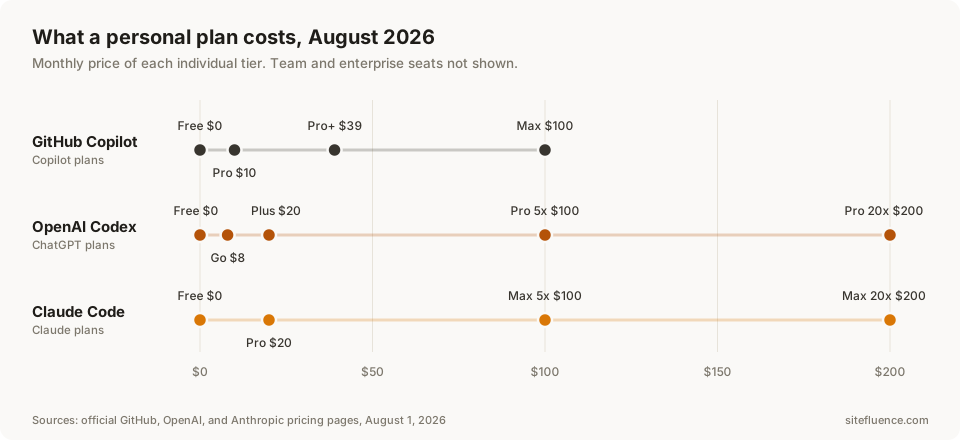
| Tier | GitHub Copilot | OpenAI Codex (ChatGPT) | Claude Code (Claude) |
|---|---|---|---|
| Free | $0, 2,000 completions, limited chat on auto model selection | $0, GPT-6 Luna in the desktop app, subject to rollout | $0, but Claude Code is not included |
| Entry | Pro $10 ($15 in AI Credits included) | Go $8, light usage | Pro $20, or $17 billed annually |
| Mid | Pro+ $39 ($70 in credits) | Plus $20 | Same Pro $20 covers it |
| Heavy | Max $100 ($200 in credits) | Pro at $100, $200, or $500 | Max $100 (5x Pro) or $200 (20x) |
| Team seat | Business $19 | Business $20 annual, $25 monthly | Team $25, or $20 annual; premium seat $125, or $100 annual |
| Enterprise seat | Enterprise $39 | Custom | $20 self-serve, or custom |
| Pay as you go | Extra credits at $0.01 each | API key at token rates, or extra credits | Claude API at token rates |
All three repriced in the first half of 2026, and in the same direction: flat subscriptions with a metered engine underneath. Copilot swapped premium requests for AI Credits on June 1. Codex moved to token-based credits on April 2, and ChatGPT added the $100 Pro tier on April 9. Anthropic doubled Claude Code's five-hour caps on May 6. Whichever you pick, you are budgeting tokens now, not seats.
Usage limits
| GitHub Copilot | OpenAI Codex | Claude Code | |
|---|---|---|---|
| Meter | AI Credits, 1 credit = $0.01, billed on tokens | Credits per token, varies by model | Time: rolling 5-hour window plus a weekly cap |
| What you get | $15/mo Pro, $70 Pro+, $200 Max; Business 1,900 credits, Enterprise 3,900 | On Plus, per 5-hour window: 5 to 45 messages on GPT-6 Astra, 15 to 160 on GPT-6.1 Sol, 15 to 150 on GPT-6 Sol, 350 to 3,000 on GPT-6 Luna; Pro plans currently have no five-hour limit | No published hour figures; Anthropic doubled the five-hour caps on May 6, 2026, and Max is 5x or 20x Pro |
| Never metered | Autocomplete and next-edit suggestions on all paid plans | Nothing | Nothing |
| When you run out | Buy credits or wait for the month | Buy credits, wait, or switch to an API key | Wait for the reset, or keep going on usage credits via /usage-credits |
| Fine print | Cloud agent also consumes Actions minutes | Local and cloud tasks share one pool; weekly caps can apply on top | Claude chat and Claude Code share the same pool |
Models
| GitHub Copilot | OpenAI Codex | Claude Code | |
|---|---|---|---|
| Native lineup | No frontier model of its own; Microsoft's MAI-Code-1.1-Flash, with MAI-Code-1-Flash retired Sep 10, 2026 and Raptor mini (tuned GPT-5 mini) retired Sep 1 | The GPT-6 family: Astra, GPT-6.1 Sol (the recommended default in config), GPT-6 Sol, and GPT-6 Luna; GPT-5.5 retires from Codex on Oct 14, 2026 and stays on the OpenAI API, GPT-5.4 retired Aug 31, 2026, and GPT-5.3-Codex-Spark retired Sep 14, 2026 | Opus 5.5 at $4 and $20 per million input and output tokens, with optional fast mode at $8 and $40; the sonnet and haiku aliases now resolve to Sonnet 5.5 and Haiku 5.5 on the Anthropic API; Fable 5.1 at $10 and $50 |
| Other vendors | The whole market: GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol and GPT-6 Luna alongside GPT-5.x, Claude from Haiku 4.5 up to Opus 5.5, Sonnet 5.5 and Fable 5.1, Gemini 3.7 and 3.8 Flash, Grok 4.5 through 4.7, Kimi K3 | No | No |
| Catches | Free and Student tiers get automatic model selection only; Claude Fable 5 and 5.1 are on Pro+, Max, Business, and Enterprise, not Pro, an org admin has to enable them, and their ZDR runs on an exemption through the end of 2026 | Astra Ultrafast is Pro $500 only, and speed modes bill at a premium: fast mode burns included usage 2.5x and credits 2x, Astra Ultrafast 8x and 6x | Fable 5.1 is opt-in via /model fable (Fable 5 by model ID), and its zero-data-retention availability follows Anthropic's Covered Models policy |
Agents and automation
| Capability | GitHub Copilot | OpenAI Codex | Claude Code |
|---|---|---|---|
| Inline autocomplete | Yes, unlimited on paid plans | No | No |
| IDE chat and agent mode | Yes | Yes, via extension | Yes, VS Code and JetBrains |
| CLI agent | Copilot CLI, all tiers | Codex CLI, open source | The original surface, fully scriptable |
| Cloud agent | Assign an issue, get a PR; 59-minute sessions, GitHub repos only | Parallel cloud tasks, kicked off from web, GitHub, Slack, or Linear | Web and mobile sessions you can pull into your terminal |
| Parallel work | One branch and PR per task | Several cloud tasks at once | Subagents and agent teams inside one session |
| Code review | Agentic PR review that can hand fixes straight to the agent | PR review inside the ChatGPT desktop app since July 9 | /review locally, GitHub Action for every PR |
| MCP support | Yes, all tiers | Yes | Yes, Anthropic wrote the spec |
| Customization | Custom instructions, Memory on paid tiers | AGENTS.md | CLAUDE.md, hooks, skills, subagents, Agent SDK |
| Scheduled runs | Cloud automations, hourly, daily, or weekly, on every paid plan | Scheduled tasks from the ChatGPT desktop app or web, not the CLI | Routines and desktop scheduled tasks |
| Hires the competition | Pro, Pro+, Max, Business, and Enterprise can delegate tasks to Claude and Codex agents (public preview) | No | No |
The personas from the first version of this post survived the data pass. Copilot is still the neighbor who knows the block, closest to your editor and your repo host. Codex is still the road-trip uncle: hand over the keys, check back later. Claude Code outgrew short errands; with subagents, hooks, and scheduled routines it is now the most customizable of the three. That part is opinion. The tables are not.
Benchmarks
| Benchmark | Best relevant results, October 2026 | What it measures |
|---|---|---|
| Terminal-Bench 4.0, official leaderboard | Claude Code with Opus 5.5 leads at 64.8%, Claude Code with Sonnet 5.5 at 61.8%, then Codex tied at 58.2% on both GPT-6 Astra and GPT-6.1 Sol, Claude Code with Fable 5.1 at 57.9%, Claude Code with Opus 5 at 53.9%, Codex with GPT-6 Sol at 49.4%, Claude Code with Fable 5 at 44.5%, Claude Code with GLM-5.3 at 41.8%, Codex with GPT-5.6 Sol at 37.3%; then Claude Code with Opus 4.8 at 23.6% and Codex with GPT-5.6 Terra at 21.5% | Agents doing real work in a terminal |
| Terminal-Bench 4.0, vendor-reported | Anthropic reported Claude Opus 5.5 at 66.4% in its own run, published with the model on September 22; the public board has since scored it at 64.8%, so the vendor claim held up to within 1.6 points | The same tasks, scored by the vendor rather than the board |
| SWE-bench Verified, vendor-reported | Claude Opus 4.8 at 88.6% | Fixing real GitHub issues |
| SWE-bench Pro, vendor-reported | Opus 4.8 at 69.2% vs GPT-5.5 at 58.6% | A harder, contamination-resistant variant |
| GitHub Copilot | No product-level entry on either board; its ceiling is whichever model you pick | n/a |
Hold the scores loosely. The order near the top moves within weeks: Codex held the board outright in September and Claude Code holds the first two places now. Vendor numbers come from tuned harnesses, the official board swapped its default from 2.1 to 4.0 on August 28 and reset every score, and on the archived 2.1 board the top two entries sit 0.6 points apart (Claude Code with Fable 5 at 83.8%, Codex with GPT-5.5 at 83.2%). The first version of this post argued you cannot benchmark a feeling. The data version of that claim: the harness you actually enjoy using matters more than two benchmark points.
Privacy and enterprise
| Question | GitHub Copilot | OpenAI Codex | Claude Code |
|---|---|---|---|
| Trains on your code? | Free, Pro, and Pro+ interaction data trains models by default, opt out in settings (a 2026 change); Business and Enterprise never | Consumer plans: opt out in data controls; Business and Enterprise: not by default | Consumer plans: your privacy setting decides; Team, Enterprise, and API: no |
| IP indemnity | Business and Enterprise; individual tiers explicitly not included | Copyright Shield, on Enterprise and the API | Included in Anthropic's commercial terms |
| Admin controls | Org-wide policies, audit logs, content exclusions, usage analytics | Workspace controls; SSO and compliance API on Enterprise | Console roles, spend caps, managed settings, zero data retention on request |
| Worth knowing | Self-serve Business signup is paused for GitHub Free and Team orgs since April 22, 2026 | Pricing changed twice this spring; recheck the rate card before budgeting | Fable 5.1's zero-data-retention availability follows Anthropic's Covered Models policy |
Which one, then
| If you | Pick |
|---|---|
| Live in your editor and want the cheapest useful upgrade | Copilot Pro at $10 |
| Already pay for ChatGPT | Codex, it is in your plan |
| Want fire-and-forget tasks from Slack or Linear | Codex |
| Want the deepest customization: hooks, subagents, MCP, an SDK | Claude Code |
| Need one bill and GitHub-native admin for a team | Copilot Business |
| Are a founder validating an idea, not shipping a platform | A $20 tier and a throwaway prototype, not a $200 tier |
| Are not sure you should be writing the code at all | Vibe-code or hire, then a $20 tier |
My honest answer in 2026 is two of them. Autocomplete and delegation are different jobs, and the vendors have stopped pretending otherwise: every paid Copilot plan can now hand tasks to Claude and Codex agents from inside GitHub. Keep Copilot for in-editor flow, add Codex or Claude Code for delegated work, and start from whichever subscription you already pay.
Prefer an open source agent that is not tied to one model vendor? OpenCode vs Claude Code vs Codex covers that. For where AI actually earns its keep, see my enterprise AI reality check.